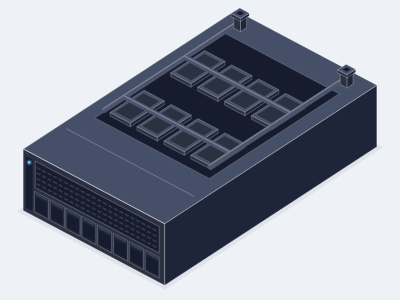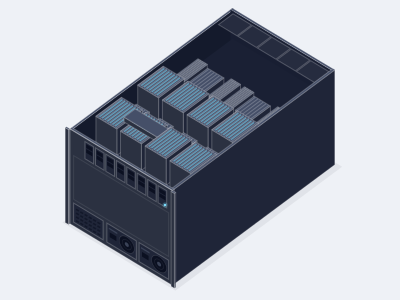
8 GPU HGX B300 AI server, air cooled
Allocation required- GPUs
- 8 x NVIDIA B300, 288 GB HBM3e each
- CPU
- 2 x AMD EPYC 9005 or 2 x Intel Xeon 6
- Memory
- Up to 3 TB DDR5 RDIMM across 24 or 32 slots
- Chassis
- 10U, about 14 kW, air cooled
NVIDIA's Blackwell Ultra 8 GPU baseboard with 288 GB HBM3e per GPU, 1.8 TB/s NVLink per GPU and integrated 800 Gb/s ConnectX-8 networking.
HGX B300 is the Blackwell Ultra generation of NVIDIA's eight GPU baseboard. Each GPU carries 288 GB of HBM3e at 8 TB/s, and the eight GPUs are joined by fifth generation NVLink and NVSwitch at 1.8 TB/s per GPU, so a single node holds a trillion parameter model in memory and serves it as one accelerator. NVIDIA publishes 144 PFLOPS of sparse FP4 and 72 PFLOPS of FP8 per baseboard, with dense FP4 1.5 times higher than HGX B200.
The baseboard integrates eight ConnectX-8 SuperNICs at up to 800 Gb/s each, so the east west fabric is part of the platform rather than an add in card. We supply HGX B300 in air cooled 10U chassis for standard racks at about 14 kW per node, and in liquid cooled chassis for high density halls. Both are quoted with AMD EPYC 9005 or Intel Xeon 6 processors, DDR5 memory, NVMe storage and BlueField-3 frontend networking.
How to decide between air and direct liquid cooling for GPU servers, from the rack power limit up to NVL72 racks that only come liquid cooled.
In this guide
The compliance steps that come with every HGX, H200 NVL, Server Edition and NVL72 purchase, explained so your order ships on time.
In this guide
A practical method for sizing an inference server from the model, the quantization and the concurrency you expect, with worked examples.
In this guide
The real differences between an HGX node and a PCIe GPU server, and a simple rule for choosing between them.
In this guide
A short guide to getting a complete, accurate quotation, from the details we need to what the quotation contains.
In this guide
Six rules of thumb that keep the GPUs fed, with the arithmetic for an 8 GPU node, a PCIe inference server and a 16 node training pod.
In this guide
We quote every class that carries it, from a single node to a pod. Tell us the workload and we propose the chassis.