
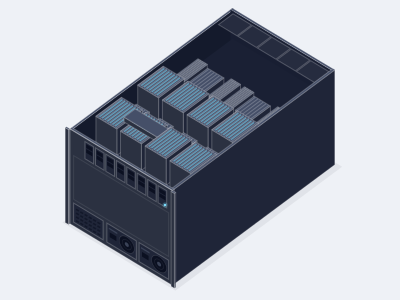
8 GPU HGX B300 AI server, air cooled
Eight NVIDIA B300 GPUs with 288 GB HBM3e each on an HGX baseboard, NVLink and NVSwitch, 8 x 800 Gb/s ConnectX-8, in a 10U air cooled chassis.
GPU: NVIDIA HGX B300
- GPUs
- 8 x NVIDIA B300, 288 GB HBM3e each, NVLink and NVSwitch
- CPU
- 2 x AMD EPYC 9005 or 2 x Intel Xeon 6
- Memory
- Up to 3 TB DDR5 RDIMM across 24 or 32 slots
- Storage
- 2 x M.2 boot, up to 8 x U.2 or E3.S NVMe
- Networking
- 8 x 800 Gb/s ConnectX-8 (east west), 2 x 400 Gb/s BlueField-3 (north south)
- Power
- Redundant PSUs, about 14 kW per node planning figure
Overview
This is the standard building block for Blackwell Ultra training and inference clusters in air cooled data centers. The HGX B300 baseboard carries eight B300 GPUs with 288 GB of HBM3e each, joined by NVLink and NVSwitch so the node behaves as one 2.1 TB accelerator. ConnectX-8 networking is integrated on the baseboard, giving each GPU its own 800 Gb/s port into the cluster fabric.
We configure the host side around your workload: dual AMD EPYC 9005 or Intel Xeon 6 processors, DDR5 memory up to 3 TB, mirrored boot drives and up to eight NVMe data drives for local checkpoints and datasets. Frontend connectivity uses BlueField-3 DPUs or ConnectX-7 adapters at 400 Gb/s for storage and north south traffic.
Every node is tested, NVLink and fabric validated, and shipped with an acceptance report. Plan for about 14 kW per node and ten rack units, which usually means three or four nodes per rack in a conventional hall. If your facility cannot support that density, ask about the liquid cooled variant, or we can lay the nodes out at a lower density that your hall or colocation facility can take.
Use cases
- LLM pretraining and continued pretraining
- Reasoning model inference at scale
- Multi node training clusters
- Fine tuning of 70B to 400B parameter models
Specifications
| GPUs | 8 x NVIDIA B300 on the HGX B300 baseboard |
|---|---|
| GPU memory | 288 GB HBM3e per GPU, 2.1 TB per node as published by NVIDIA |
| GPU interconnect | Fifth generation NVLink, 1.8 TB/s per GPU, NVSwitch |
| FP4 performance | 144 PFLOPS sparse, 108 PFLOPS dense per node |
| CPUs | 2 x AMD EPYC 9005 series or 2 x Intel Xeon 6, up to 128 cores per socket class |
| System memory | 24 or 32 x DDR5 RDIMM, up to 3 TB |
| Boot | 2 x M.2 NVMe, mirrored |
|---|---|
| Data | Up to 8 x U.2 or E3.S NVMe, 7.68 TB to 30.72 TB each |
| RAID | Software RAID or optional hardware RAID for boot volume |
| GPU fabric | 8 x 800 Gb/s InfiniBand or RoCE, ConnectX-8, OSFP |
|---|---|
| Frontend | 2 x 400 Gb/s, BlueField-3 or ConnectX-7, QSFP112 |
| Management | Dedicated 1 GbE BMC port, TPM 2.0 |
| Form factor | 10U rackmount, air cooled, front to back airflow |
|---|---|
| Power supplies | Redundant 3,000 W class PSUs, 200 to 240 V input |
| Planning power | About 14 kW per node |
| Inlet temperature | Up to 35 C class, check site conditions |
Figures describe the system class. Exact configuration, weights and power draw are confirmed on the quotation.
What's included
- Rails, power cords and cable management arm
- Burn in with multi hour GPU stress and NVLink validation, acceptance report
- NVIDIA end user registration handled with the order
- Operating system imaging, driver and fabric manager baseline on request
- 3 year warranty, options to 5 years with advance replacement
Compliance
Related
Related systems
8 GPU HGX B300 AI server, liquid cooled
Allocation required- GPUs
- 8 x NVIDIA B300, 288 GB HBM3e each
- CPU
- 2 x AMD EPYC 9005 or 2 x Intel Xeon 6
- Memory
- Up to 3 TB DDR5 RDIMM
- Chassis
- 4U, about 14 kW, liquid cooled
8 GPU HGX B200 AI server
- GPUs
- 8 x NVIDIA B200, 180 GB HBM3e each
- CPU
- 2 x AMD EPYC 9005 or 2 x Intel Xeon 6
- Memory
- Up to 3 TB DDR5 RDIMM
- Chassis
- 8U, about 14 kW, air cooled
8 node HGX B300 AI pod, 64 GPUs
Allocation required- GPU nodes
- 8 x 8 GPU HGX B300 servers, 64 x B300
- Fabric
- 64 x 800 Gb/s ports, non blocking
- CPU and control
- 2 x CPU nodes for data services
- Chassis
- Multi rack, about 125 kW, air cooled
800G Quantum-X800 InfiniBand switch
- Ports
- 144 x 800 Gb/s XDR InfiniBand through 72 OSFP cages
- Throughput
- 115.2 Tb/s aggregate switching
- In network computing
- SHARP fourth generation, adaptive routing
- Form factor
- 4U, air cooled
Related guides
Air cooled vs liquid cooled AI servers
How to decide between air and direct liquid cooling for GPU servers, from the rack power limit up to NVL72 racks that only come liquid cooled.
In this guide
- The question is the rack, not the server
- How air cooling works at high density
Buying data center GPUs, export and registration
The compliance steps that come with every HGX, H200 NVL, Server Edition and NVL72 purchase, explained so your order ships on time.
In this guide
- Why a GPU purchase comes with paperwork
- Which products are covered
Choosing a GPU server for LLM inference
A practical method for sizing an inference server from the model, the quantization and the concurrency you expect, with worked examples.
In this guide
- Start with the model, not the server
- Step 1: how much GPU memory the weights need
HGX vs PCIe GPU servers
The real differences between an HGX node and a PCIe GPU server, and a simple rule for choosing between them.
In this guide
- Two kinds of 8 GPU server
- The interconnect is the point
Compare it with the next class up or down
The nearest classes we quote are the 8 GPU HGX B300 AI server, liquid cooled and the 8 GPU HGX B200 AI server. If neither is quite right, tell us the workload and we specify the system between them.
- (858) 613-1818
- sales@computermodules.com
- Monday to Friday, 8am to 5pm Pacific