
8 GPU HGX B300 AI server, liquid cooled
Direct liquid cooled HGX B300 node in a 4U chassis with eight B300 GPUs, NVLink and NVSwitch, 8 x 800 Gb/s ConnectX-8, built for high density racks.
GPU: NVIDIA HGX B300
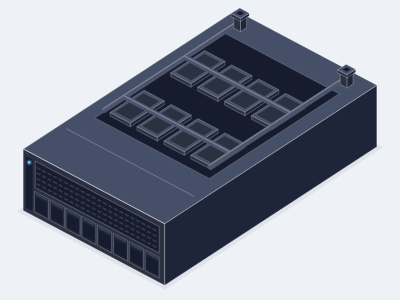
- GPUs
- 8 x NVIDIA B300, 288 GB HBM3e each, NVLink and NVSwitch, cold plates on GPUs and switches
- CPU
- 2 x AMD EPYC 9005 or 2 x Intel Xeon 6, liquid cooled
- Memory
- Up to 3 TB DDR5 RDIMM
- Storage
- 2 x M.2 boot, up to 8 x E3.S NVMe
- Networking
- 8 x 800 Gb/s ConnectX-8 (east west), 2 x 400 Gb/s BlueField-3 (north south)
- Cooling
- Direct to chip, facility water through rack manifold and CDU
Overview
The liquid cooled HGX B300 node puts the same eight B300 GPUs, NVLink domain and ConnectX-8 fabric into a 4U chassis with cold plates on the GPUs, NVSwitch and CPUs. Heat goes to facility water through quick disconnects and a rack manifold, so eight or more nodes fit in one rack and the GPUs can run at their full rated power without acoustic or airflow limits.
It is the right choice for new halls designed around liquid cooling and for high density retrofits where a coolant distribution unit can be added. We quote the node with the rack manifold, the CDU sizing and the remaining air cooled share so that the facility design has a complete heat budget rather than a per node figure alone.
Host configuration mirrors the air cooled class: dual AMD EPYC 9005 or Intel Xeon 6, DDR5 memory to 3 TB, mirrored boot and up to eight E3.S data drives, and 400 Gb/s BlueField-3 frontend. Burn in is carried out on a liquid test bench before shipment and the acceptance report includes leak testing and coolant flow checks.
Use cases
- High density LLM training clusters
- Liquid cooled AI factories
- Dense inference fleets
- Retrofits with rack level CDUs
Specifications
| GPUs | 8 x NVIDIA B300 on the HGX B300 baseboard |
|---|---|
| GPU memory | 288 GB HBM3e per GPU, 2.1 TB per node as published by NVIDIA |
| GPU interconnect | Fifth generation NVLink, 1.8 TB/s per GPU, NVSwitch |
| CPUs | 2 x AMD EPYC 9005 series or 2 x Intel Xeon 6 |
| System memory | 24 or 32 x DDR5 RDIMM, up to 3 TB |
| Boot | 2 x M.2 NVMe, mirrored |
|---|---|
| Data | Up to 8 x E3.S NVMe, 7.68 TB to 15.36 TB each |
| Expansion | Shared storage over the 400 Gb/s frontend network |
| GPU fabric | 8 x 800 Gb/s InfiniBand or RoCE, ConnectX-8, OSFP |
|---|---|
| Frontend | 2 x 400 Gb/s, BlueField-3, QSFP112 |
| Management | Dedicated 1 GbE BMC port, TPM 2.0 |
| Form factor | 4U rackmount, direct liquid cooled |
|---|---|
| Liquid loop | Cold plates on GPUs, NVSwitch and CPUs, quick disconnects to rack manifold |
| Heat to liquid | Roughly 80 percent of node heat rejected to facility water, remainder to air |
| Planning power | About 14 kW per node, with GPUs able to run at full TGP |
| Power supplies | Redundant PSUs, 200 to 240 V input |
Figures describe the system class. Exact configuration, weights and power draw are confirmed on the quotation.
What's included
- Rails, power cords and cable management arm
- Burn in with multi hour GPU stress and NVLink validation, acceptance report
- NVIDIA end user registration handled with the order
- Operating system imaging, driver and fabric manager baseline on request
- 3 year warranty, options to 5 years with advance replacement
- Rack manifold connectors and leak test certificate
Compliance
Related
Related systems
8 GPU HGX B300 AI server, air cooled
Allocation required- GPUs
- 8 x NVIDIA B300, 288 GB HBM3e each
- CPU
- 2 x AMD EPYC 9005 or 2 x Intel Xeon 6
- Memory
- Up to 3 TB DDR5 RDIMM across 24 or 32 slots
- Chassis
- 10U, about 14 kW, air cooled
16 node HGX B300 AI pod, 128 GPUs
Allocation required- GPU nodes
- 16 x 8 GPU HGX B300 servers, 128 x B300
- Fabric
- 128 x 800 Gb/s ports, leaf and spine
- CPU and control
- 3 x CPU nodes for data services
- Chassis
- Multi rack, about 245 kW, air or liquid cooled
NVIDIA GB300 NVL72 rack
Allocation required- GPUs
- 72 x NVIDIA Blackwell Ultra, 288 GB HBM3e each
- CPUs
- 36 x NVIDIA Grace, 2,592 Arm Neoverse V2 cores
- NVLink
- 130 TB/s total NVLink bandwidth across all 72 GPUs
- Chassis
- Single rack, power not yet published, liquid cooled
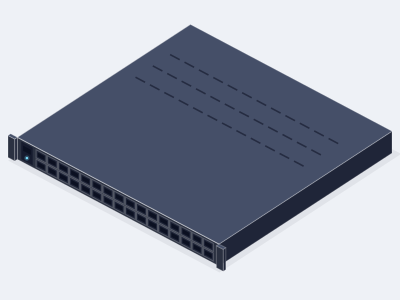
800G Quantum-X800 InfiniBand switch
- Ports
- 144 x 800 Gb/s XDR InfiniBand through 72 OSFP cages
- Throughput
- 115.2 Tb/s aggregate switching
- In network computing
- SHARP fourth generation, adaptive routing
- Form factor
- 4U, air cooled
Related guides
Air cooled vs liquid cooled AI servers
How to decide between air and direct liquid cooling for GPU servers, from the rack power limit up to NVL72 racks that only come liquid cooled.
In this guide
- The question is the rack, not the server
- How air cooling works at high density
Buying data center GPUs, export and registration
The compliance steps that come with every HGX, H200 NVL, Server Edition and NVL72 purchase, explained so your order ships on time.
In this guide
- Why a GPU purchase comes with paperwork
- Which products are covered
Choosing a GPU server for LLM inference
A practical method for sizing an inference server from the model, the quantization and the concurrency you expect, with worked examples.
In this guide
- Start with the model, not the server
- Step 1: how much GPU memory the weights need
HGX vs PCIe GPU servers
The real differences between an HGX node and a PCIe GPU server, and a simple rule for choosing between them.
In this guide
- Two kinds of 8 GPU server
- The interconnect is the point
Compare it with the next class up or down
The nearest classes we quote are the 8 GPU HGX B300 AI server, air cooled and the 16 node HGX B300 AI pod, 128 GPUs. If neither is quite right, tell us the workload and we specify the system between them.
- (858) 613-1818
- sales@computermodules.com
- Monday to Friday, 8am to 5pm Pacific