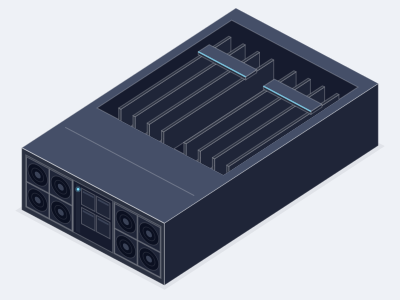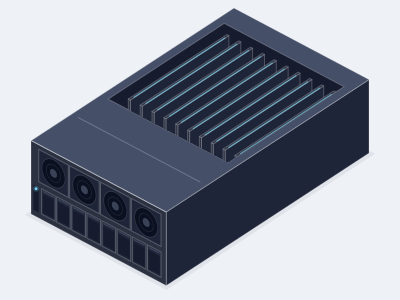
8 GPU RTX PRO 6000 PCIe AI server
- GPUs
- 8 x RTX PRO 6000 Blackwell Server Edition
- CPU
- 2 x AMD EPYC 9005 or 2 x Intel Xeon 6
- Memory
- Up to 2 TB DDR5 RDIMM
- Chassis
- 4U, about 6.5 kW, air cooled
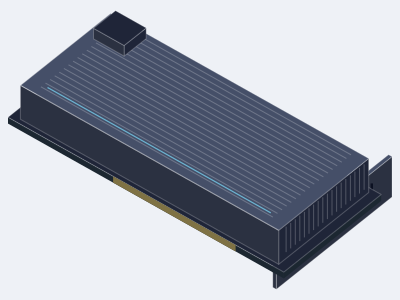
The Blackwell data center PCIe GPU with 96 GB GDDR7 ECC, 24,064 CUDA cores, 4 PFLOPS FP4 and 400 to 600 W, for air cooled servers with up to ten GPUs.
RTX PRO 6000 Blackwell Server Edition is the passively cooled, data center version of NVIDIA's Blackwell workstation GPU. It carries 96 GB of GDDR7 with ECC at 1.6 TB/s, 24,064 CUDA cores, fifth generation Tensor cores with 4 PFLOPS of FP4, and 188 fourth generation RT cores. Power is configurable between 400 W and 600 W, and the card supports Multi Instance GPU with up to four isolated instances.
Because it is a dual slot PCIe card without NVLink, it suits servers that pack two to ten GPUs for inference, fine tuning of models up to roughly 70B parameters with tensor parallelism over PCIe, media and rendering farms, and virtual workstations. Four NVENC and four NVDEC engines make it strong for video pipelines. We supply it in 2U, 4U and 5U PCIe servers and as an individual card, subject to end user registration.
The compliance steps that come with every HGX, H200 NVL, Server Edition and NVL72 purchase, explained so your order ships on time.
In this guide
A practical method for sizing an inference server from the model, the quantization and the concurrency you expect, with worked examples.
In this guide
The real differences between an HGX node and a PCIe GPU server, and a simple rule for choosing between them.
In this guide
A short guide to getting a complete, accurate quotation, from the details we need to what the quotation contains.
In this guide
Workstation, Max-Q and Server Edition share one GPU and 96 GB of memory; this guide explains what differs and which to buy for a desk, a dense workstation or a rack.
In this guide
Six rules of thumb that keep the GPUs fed, with the arithmetic for an 8 GPU node, a PCIe inference server and a 16 node training pod.
In this guide
We quote every class that carries it, from a single node to a pod. Tell us the workload and we propose the chassis.